Nº06 · MITModel internals · 2026模型内部结构 · 2026
LLM Arch Cards
What is inside an open-weight model, read from its config and checked against the Hub.只读配置文件,拆解开源模型的内部结构,并与 Hub 交叉核对。
config only · 0 weights
01Problem问题
Choosing a model for a GPU box means knowing its attention layout, KV-cache cost and real parameter count, before spending an hour downloading weights.为一台 GPU 机器选模型,需要在花一小时下载权重之前,先知道它的注意力结构、KV 缓存成本和真实参数量。
02Flow流程
- HF configHF 配置
- meta devicemeta 设备
- Module tree模块树
- Matches the Hub?与 Hub 一致?
- Architecture card架构卡片
03What I built我做了什么
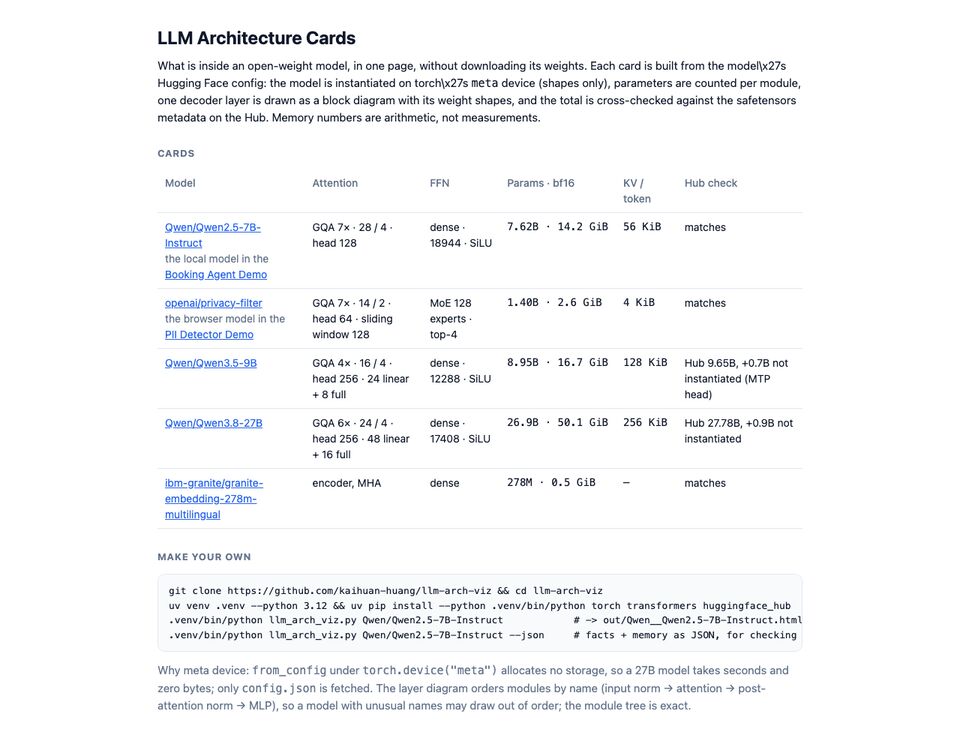
- Instantiate the model on torch's
metadevice (shapes only), so a 70B model takes seconds and zero disk.在 torch 的meta设备上实例化(只有形状),70B 模型也只需几秒、零磁盘。 - Render attention kind, FFN or MoE, layer schedule, one decoder layer with weight shapes, and memory arithmetic for bf16 / int8 / int4.渲染注意力类型、FFN 或 MoE、层调度、带权重形状的单个解码层,以及 bf16 / int8 / int4 的内存估算。
- Cross-check the parameter total against the Hub's safetensors metadata and explain any delta.与 Hub 的 safetensors 元数据交叉核对参数总量,并解释差异。
04Measured测量结果
05Limits, stated plainly局限,直说
- Memory figures are arithmetic, not measurements. No automated tests yet.内存数字是计算值而非实测;尚无自动化测试。