Nº01 · EN / 中文Bilingual LLM booking agent · 2026双语 LLM 预订助手 · 2026
Booking Agent
Books only on an explicit yes. Rules, not the model, fill every booking field.只有客人明确说“是”才下单;每个预订字段都由规则而不是模型填写。
33/39 held-out · 31 tests
01Problem问题
An LLM-only pilot of Nalu got 17 of 30 messages fully right (57%) and invented booking values that guests never gave. A wrong party size or time is a real table problem on a Friday night.Nalu 的纯 LLM 试点只有 17/30 条消息完全正确(57%),还会编造客人没给的预订值。人数或时间错了,周五晚上就是真实的桌位事故。
02Flow流程
- Guest message客人消息
- Rules read fields规则读字段
- Ask if unclear不清楚就问
- Explicit yes?明确说“是”?
- create_reservation · pendingcreate_reservation · 待确认
03What I built我做了什么
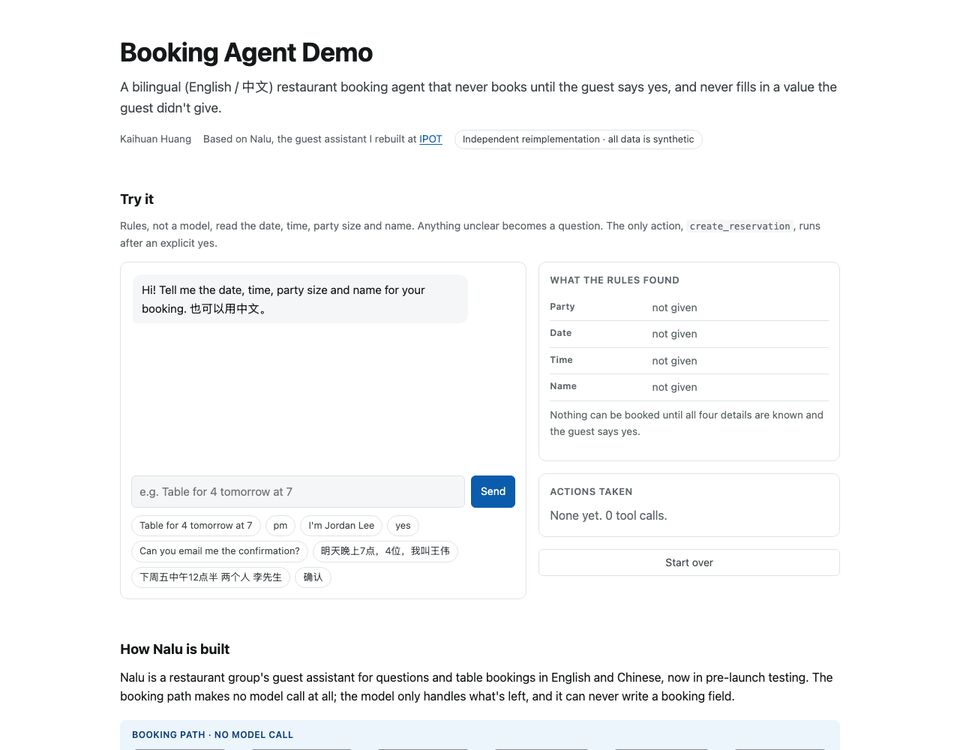
- Rules, not a model, read date, time, party size and name. Anything ambiguous (“at 7”) becomes a question.日期、时间、人数和姓名由规则读取,不交给模型;任何含糊处(“7 点”)都变成追问。
- One action,
create_reservation, runs only after a bare, explicit yes. “ok” or “好” asks again. The result stays pending until the restaurant confirms.唯一的动作create_reservation只在明确的“是”之后执行;“ok”“好”会再问一次。结果在餐厅确认前保持 pending。 - With Ollama running locally, the page asks your own model to read the same conversation and marks where it guessed.本地运行 Ollama 时,页面会让你自己的模型读同一段对话,并标出它猜测的地方。
04Measured测量结果
17/30 · 33/39
model-only pilot (30 cases) · rules + gate on a separate held-out set (39 cases); not a like-for-like before and after纯模型试点(30 例)· 规则 + 确认闸门在另一份留出集上(39 例);两者不是严格可比的前后对照
31
synthetic conversations run as tests in the browser在浏览器中作为测试运行的合成对话
114 / 0
live replay turns / failures on Nalu (23 conversations × 3 runs)Nalu 实时回放轮数 / 失败数(23 段对话 × 3 次)
05Limits, stated plainly局限,直说
- The 33/39 and replay numbers were measured on Nalu, not on this demo; the demo reproduces the design on synthetic data.33/39 和回放数据测自 Nalu,而不是本演示;演示用合成数据复现同一设计。
- The model comparison needs a local Ollama, so most visitors see only the rules path.模型对比需要本地 Ollama,大多数访客只能看到规则路径。